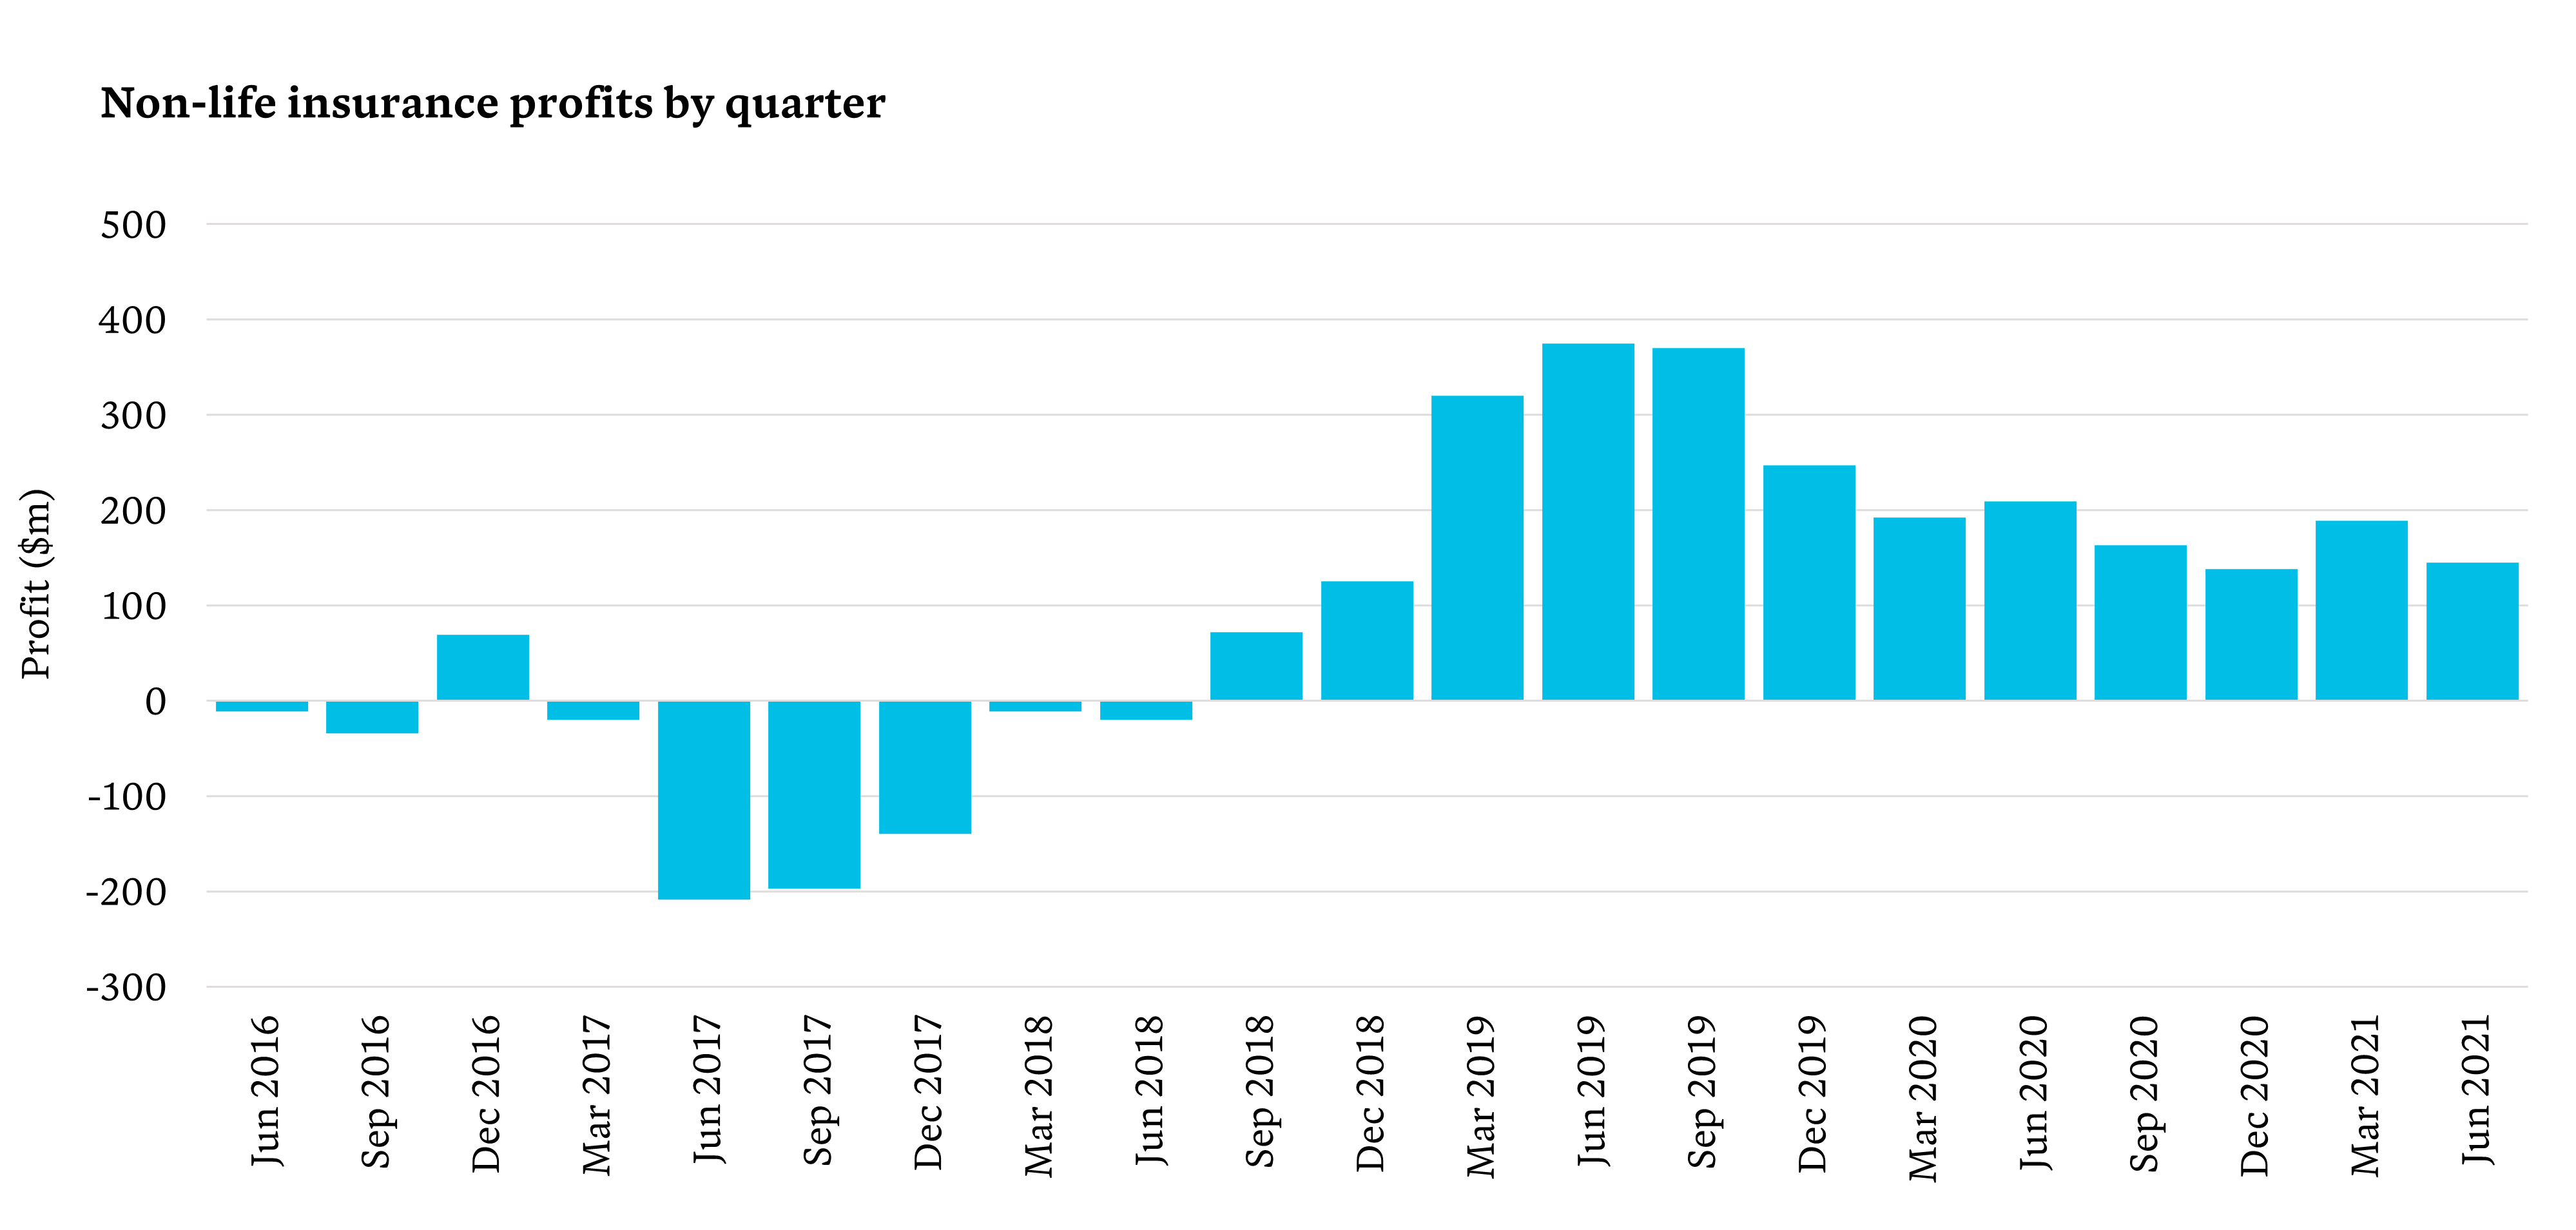Category: Uncategorized

  • International modelling win for Taylor Fry Director

    Fun is not generally an experience most people associate with maths and spreadsheets, but for Andrew Ngai, who has won the 2021 Financial Modeling World Cup (FMWC) Open tournament, it’s the perfect word.

    The international competition is a fierce knock-out event, gathering 128 of the sharpest quantitative minds from around the world in seven 30-minute rounds of Excel problem solving over the course of a week. In the final, Andrew, a Director at Taylor Fry, won against Canadian Michael Jarman to take home $3000 in prize earnings.

    “For me, it’s a lot of fun solving the problems, and I’m glad it was entertaining for our audience as well,” says Andrew. “The organisers put in a lot of effort to create fun and interesting cases, such as building a model to play classic games like dominos, snake or battleships. It’s also in Excel, which suits me well because I use Excel all the time at work and even just generally in my life.”

    Andrew Ngai met head-to-head with some strong competitors in the knock-out event

    As for preparation or nerves, these don’t factor in too heavily for Andrew, despite the high-pressure stakes. “My day-to-day actuarial job is a good training ground and gives me most of the practice I need,” he says. The trickiest part is waking up in time for a fresh 4am start. “It’s hard to find a timeslot that works well for all participants and viewers across the globe, and this time it meant an early morning start for me – and we were livestreamed on YouTube and ESPN, so no pyjamas either.”

    Andrew also took part in the FMWC regular competition, which focused on financial modelling, again in Excel. Attending the 12 two-hour sessions it involved over the year, Andrew placed third on the global leader board in the final world rankings for 2021.

    While these types of competitions have been a perfect blend of Andrew’s skillset and having fun, he has also appreciated the chance to meet like-minded people from all over the world. “It’s a pretty niche area,” Andrew says. “So it’s also been great to meet people over the years who share such a specialised interest.”

  • The role of data in disrupting disadvantage

    The Committee for Economic Development of Australia, CEDA, has released its latest report, Disrupting Disadvantage Part 2, focusing on how federal and state governments can adopt a data-led approach in helping to ‘stop children from being locked into a cycle of poverty’.

    In the first chapter of the report, Taylor Fry’s Peter Mulquiney, Laura Dixie and Andrew Ngai explore the benefits of analysing linked Commonwealth and state datasets, such as better targeted support and effective early intervention for this vulnerable group.

    We explain how governments can derive value from the vast array of administrative data they collect from human services, such as education, healthcare, income support, social housing, justice and child protection.

    Linked administrative data enables a focus on early intervention to support young Australians

    When linked together in a careful and responsible way, we show how this data can be used to provide a rich picture of the paths, predictors and preventors of entrenched disadvantage. We discuss in further detail:

    • Role of data to detect and support young Australians at risk of falling into entrenched disadvantage
    • Different types of data
    • Variables necessary in the early detection of future persistent disadvantage
    • Predictive factors
    • Progress to date for linked data
    • The role of the private sector
    • Technical and political challenges.
  • New Zealand general insurance update 2021 – weather, regulation and affordability high on insurers’ minds

    As another pandemic year draws to a close, we look back at the events and thinking that shaped the New Zealand general insurance experience. The issues ahead will provide plenty of challenge as leaders tackle climate change, a raft of new compliance changes and increased government scrutiny to ensure a healthy marketplace.

    Floods, hailstorms, tornadoes and the Lake Ohau fire, which destroyed 48 homes, caused insurers to take a profitability hit in FY2021. According to the Insurance Council of New Zealand natural disaster list, there were nine major events across Aotearoa estimated at $213 million in total losses. Despite these figures, quarterly data from the Reserve Bank of New Zealand (RBNZ) shows that although the level of profits have declined, general insurers remained profitable over the past year.

    This continued profitability of insurers, even with an increase in the number of natural disasters, indicates that past rate increases have resulted in insurers having adequate pricing and reinsurance programs. However, further premium rate increases are likely in the country due to increasing reinsurance rates, with the New Zealand general insurance market covered by a few reinsurers able to pick and choose their exposures. This is in line with hardening premium rates internationally, as consumer demand remains high, while insurer supply and appetite dwindle.

    Source: RBNZ Quarterly Insurance Financial Performance

    Greater focus on flood risk

    Weather-related events have also continued into the second half of 2021, with heavy rain in mid-July causing significant flooding across the country, but with the West Coast being the hardest hit. The current costs for these floods are in excess of $120 million. West Auckland also experienced severe flooding in August 2021.

    These events highlight that flood risk is significant for New Zealand general insurance. To date, the introduction of risk-based pricing in the New Zealand market has predominantly focused on earthquake risks. This is due to the higher risk of large losses posed by earthquakes and the availability of sophisticated insurance risk models for earthquakes. Historically, flood models that cover all New Zealand risks have not been available.

    In May 2021, RMS, an international catastrophe risk-modelling firm, launched a flood model for New Zealand. In June 2021, financial and data services company CoreLogic updated its flood models that were launched in 2020 to providing 100 per cent coverage and greater detail, down to property level. As the sophistication of risk modelling increases, insurers will be able to adjust their pricing and underwriting to reflect a wider range of risks.

    When risk-based pricing gets sophisticated

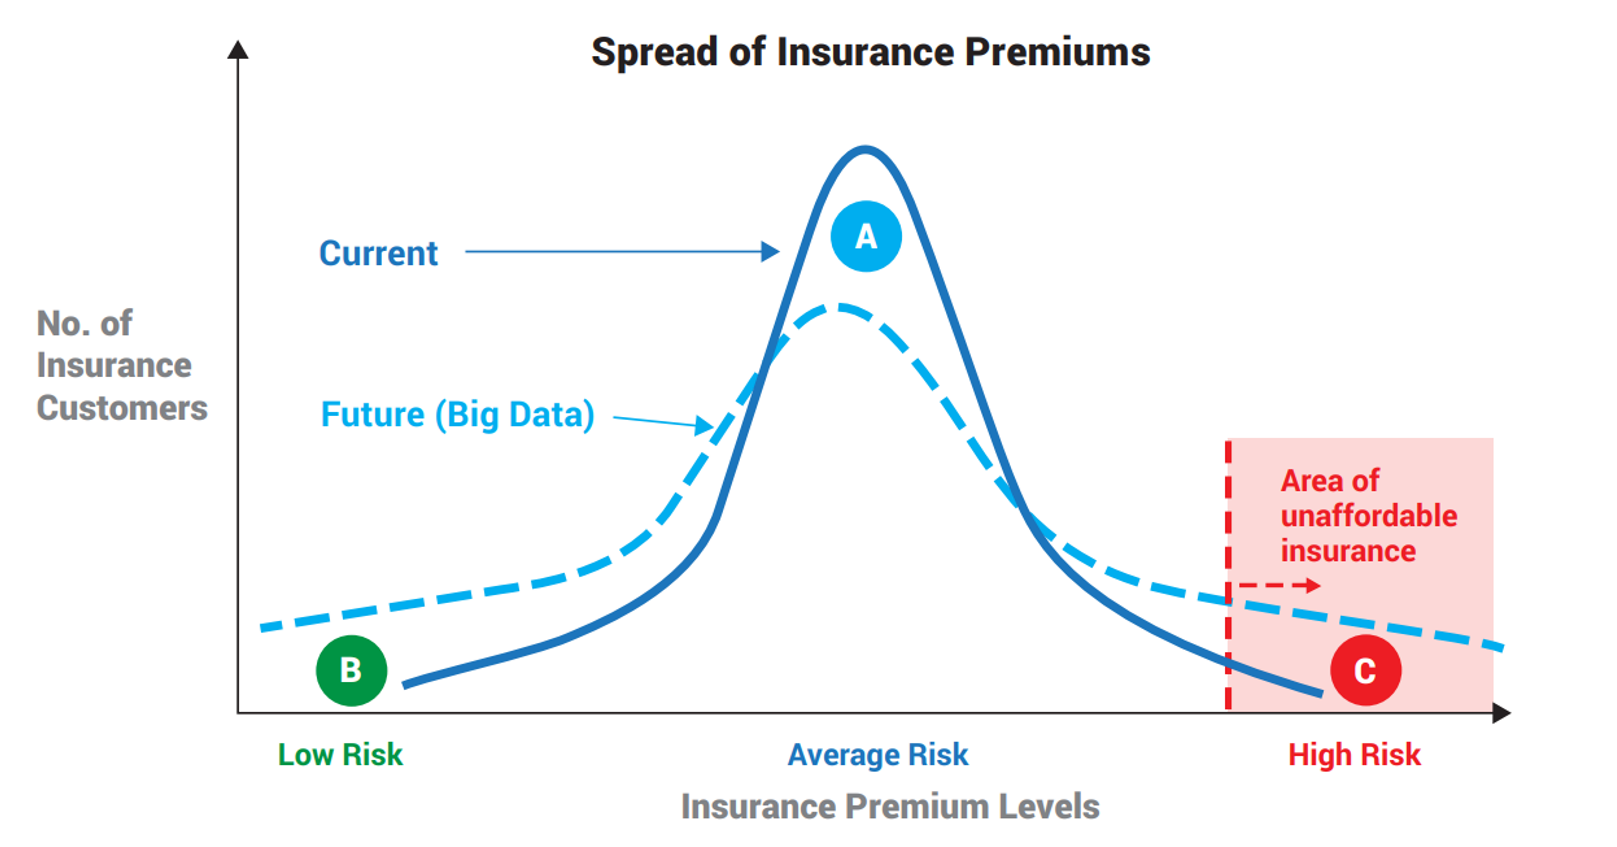
    This broadening of risk-based pricing will result in a wider spread of insurance premiums, which means some customers will see a decrease in their premiums and others will see their premiums increase. Those customers that experience the largest premium increases may potentially end up being unable to afford to continue to insure their property.

    When increases in risk-pricing results in homes becoming unaffordable, this can result in pressure for the Government to intervene in the insurance market. An example of this is the reinsurance pool for North Australian cyclones and floods, which was announced by the Australian Government in May. With the exception of the Earthquake Commission (EQC), we are yet to see any similar interventions in New Zealand.

    Source: The Impact of Big Data on the Future of Insurance, Actuaries Institute of Australia

    Warning bells for coastal retreats

    One future risk that the Government is considering is coastal erosion. As sea levels rise due to global warming, several coastal properties are expected to become uninsurable. A paper published through the Government’s Deep South Challenge initiative estimated that up to 10,000 homes may be uninsurable by 2050. Minister for Climate Change James Shaw has said the Government will be looking at the options to tackle sea-level rise as part of the Climate Change Adaptation Act (CCA), one of the three acts government is proposing to replace the Resource Management Act.

    One of the potential options in response to rising sea levels is managed retreat, where coastal properties are abandoned, and people are resettled in new properties. James Shaw has said the Government hasn’t made any policy decisions yet. However, the Ministry for the Environment’s website says that the CAA will “address the complex and technical issues associated with managed retreat and funding and financing adaptation”. This suggests some form of managed retreat will be implemented. The Government will work closely with insurers and banks in the development of the CCA. There is currently no firm date for when the CCA will be implemented.

    Mandatory climate-related disclosures

    In the more immediate term, the Government has also announced the introduction of mandatory climate-related disclosures for large insurers. This requirement will apply to licensed insurers with annual premiums of more than $250 million or assets of more than $1 billion. This definition will capture the nine largest general insurers in New Zealand, along with the two largest health insurers. However, insurers who are not captured by the requirements could potentially self-adopt the requirements as well.

    At the moment, there are no requirements for reporting on climate change impacts. The Productivity Commission noted in its Low Emissions Economy report that this lack of information has resulted in “ongoing and systemic overvaluation of emissions-intensive activities”. One of the goals of the mandatory disclosures is “to ensure that the effects of climate change are routinely considered in business, investment, lending and insurance underwriting decisions”.

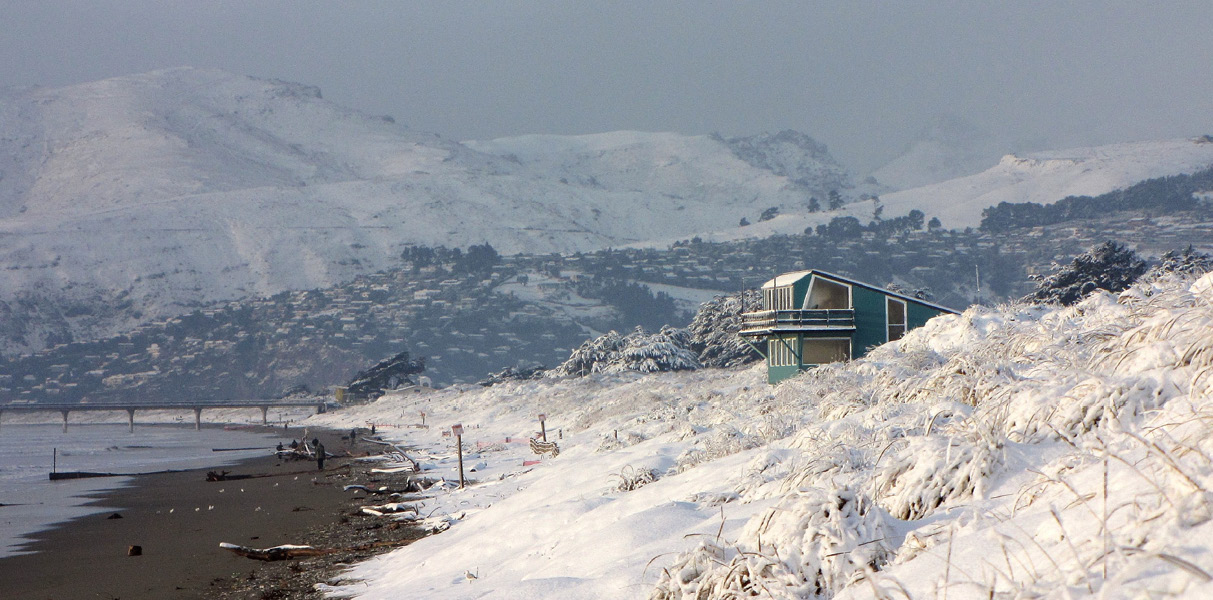
    Future risk: government is considering coastal erosion, as sea levels rise with global warming

    The requirements of the mandatory disclosure are being developed by the External Reporting Board (XRB). The standards will be based on the 2017 recommendations from the Task Force on Climate-related Financial Disclosures of the Financial Stability Board. These recommendations have four key themes:

    • Governance of climate-related risks
    • The impact that climate-related risks have on an organisation’s strategy and resilience
    • The risk-management processes an organisation has for identifying and managing climate-related risks
    • The metrics and targets are used to assess and manage climate-related risks.

    The XRB are currently consulting on the proposed governance and risk management sections of the proposed new standard. Further consultation on the strategy and metrics and targets sections of the standard will be held in March 2022. A final consultation on the formal exposure draft will then be held in July 2022, with the final standard expected to be issued in December 2022.

    New standard bearers

    In July, the RBNZ published the draft Interim Solvency Standards (ISS), as part of its solvency standards review announced in October 2020. The review of the solvency standards is seeking to respond to several developments that have emerged since the standards were first introduced in 2014. Two of the key developments are the introduction of new insurance accounting standards and the IMF review of the New Zealand financial sector, which recommended closer adherence to the International Association of Insurance Supervisors’ Insurance Core Principles.

    The draft ISS combines the five current solvency standards into a single standard. Combining the standards has created some definitional issues between general and life insurance contracts. The definitions outlined in the ISS mean that New Zealand general insurance products that have terms of more than one year, such as extended warranty insurances which usually have terms of 3-5 years, are considered long-term insurance and so would be subject to solvency standard requirements from the old life insurance standard.

    Waiting for change

    At this stage, there have been no changes to the existing calibration factors that are used to calculate the minimum solvency capital for general insurers. The ISS was not intended to alter capital requirements. The RBNZ will be undertaking a recalibration of the capital changes in stage two of the solvency standard review, which is expected to be done in 2022 and 2023. However, the standard includes a new capital charge for operational risk, which will impact the regulatory solvency position for general insurers.

    Freeze frame: mandatory climate-related disclosures will capture the nine largest general insurers

    The operational risk charge is calculated as three per cent of an insurer’s gross premium (or their claims liabilities, if these are higher), plus an additional charge for insurers who have annual premium growth that exceeds 20 per cent. For the 10 largest general insurers who comply with New Zealand solvency requirements, applying this charge to their last annual accounts would result in a 36 per cent decrease in their combined solvency ratios. This may suggest insurers could look to increase their capital levels, potentially by increasing the retention of any future profits.

    The RBNZ is considering feedback from the submissions on the draft ISS and is aiming to publish a revised ISS by 1 October 2022. The draft ISS was originally due to come into force on 1 January 2022, but has been deferred until 1 January 2023.

    Conduct bill on the horizon

    The other piece of regulation on the horizon for New Zealand general insurance is the Financial Markets (Conduct of Institutions) Amendment Bill (CoFI), which will amend the Financial Markets Conduct Act 2013. The CoFI bill will require insurers to have a fair conduct program to ensure they treat customers fairly. It will also regulate sales incentives, with incentive targets likely to be banned. The CoFI bill is awaiting its second reading in parliament and is expected to pass into law in 2023.

    In July, the Financial Markets Authority (FMA), which will be the regulator of insurers’ fair conduct programs under the CoFI bill, issued a report on how general insurers are responding to conduct risk. In particular, the report looked at whether general insurers had completed a set of specific FMA-requested tasks, relating to their conduct risk, commissions and incentives. The report found only two insurers had completed the tasks to the FMA’s satisfaction. This suggests general insurers will still have some work to do in meeting their regulatory requirements under CoFI once it is enacted.

    Under pressure: RBNZ stress testing found insurers would be most affected by a reinsurance shock

    Stress-test first reveals reinsurance weak link

    The RBNZ recently released its findings of the first stress test it has undertaken on general insurers. It put the five largest insurers to the test covering three scenarios: a reinsurance market stress scenario, an economic downturn scenario and a severe weather events scenario.

    The stress testing found insurers would be most impacted by the reinsurance market stress scenario. Under this scenario, it is assumed that due to catastrophic global events the global reinsurance market experiences a shock. The result of this shock is a 10 per cent reduction in reinsurance capacity, together with increasing reinsurance premiums and credit rating downgrades for reinsurers. Under this scenario, the New Zealand general insurance industry would fail the RBNZ’s regulatory solvency requirements if no mitigating actions were undertaken by insurers.

    The reason for this result is the RBNZ’s requirement for general insurers to obtain reinsurance cover for expected losses from a 1:1000 earthquake event. For all other risks, reinsurance is needed only for expected losses from a 1:250-year event. This means that insurers who underwrite earthquake risks are reliant on reinsurers providing high levels of cover.

    Tricky choice – cover the cost or exclude the risk

    A reduction in global reinsurance capacity would mean that insurers would need to either raise capital to cover the reduced reinsurance capacity or reduce their exposure to earthquake risks. The RBNZ stress-testing results show that the additional capital that would need to be raised by the five largest insurers is $1.9 billion for a 10 per cent reduction in reinsurance capacity. Under this scenario, one potential mitigating option for insurers would be to exclude earthquake cover for property risks or provide it as a highly priced optional extra, as is the case in California. This scenario could lead to public pressure on the Government to carry all earthquake risks through the EQC, including commercial risks, which are currently not covered.

    Future perspective: the NZ insurance landscape is well placed to navigate the challenges ahead

    Earthquake Commission has an eye for fairness

    Prior to the results of the RBNZ stress testing, the Government has announced it will be increasing the EQC cap for domestic properties, from the current $150,000 to $300,000 (plus GST). This increase will mean that the maximum EQC levies increase from $345 to $552. The change will come into effect for policies written from 1 October 2022. The Government has said it expects to see insurance premiums reduce, and that if insurers’ pricing does not behave as expected, then it is open to considering options, such as a competition study.

    The increase in the EQC cap will reduce the private insurance industry’s exposure to domestic earthquake risks. This would reduce the magnitude of the reinsurance market test highlighted by the RBNZ stress testing, although it would be unlikely to change the underlying result. However, the majority of the domestic market is insured by either IAG or Suncorp. Both insurers have reinsurance programs covering their combined New Zealand and Australian risks. This means the change in the risk exposure for their New Zealand risks may not necessarily result in a reduction in their overall reinsurance costs. Internationally, reinsurance rates are also expected to increase over the next year. This is due to higher-than-usual numbers of natural catastrophe losses globally, as well as losses related to the COVID-19 pandemic.

    Given these factors and the Government messaging, we expect the pricing of domestic insurance policies for the next few years to be under a higher-than-usual level of scrutiny. This, combined with the expected introduction of the CoFI legislation, will require insurers to provide more evidence they are treating customers fairly.

    The future is agile

    A wave of change is bearing down on the New Zealand general insurance industry and insurers will need to respond to several regulatory changes. These changes will increase the compliance costs for insurers. At the same time, insurance affordability will continue to remain a key issue. The insurance industry is well placed to respond to these changes, but will need to keep in mind the importance of a flexible approach in this fast-changing environment.

  • Hugh Miller named 2021 Actuary of the Year

    We’re delighted to announce that Taylor Fry Principal Hugh Miller has been awarded 2021 Actuary of the Year, by the Actuaries Institute.

    From his earliest days as a graduating student, taking home the University of Sydney’s University Medal in 2005, Hugh was already hinting at a distinguished career to come. He has been a tireless and exemplary role model for the actuarial profession – a powerful voice for excellence, thought leadership and the potential for actuaries to make a tangible difference in society.

    Focusing primarily on the social sector, Hugh uses data in actuarial and advanced analytics projects to improve government policy across employment, welfare, disability and homelessness. This work has helped break ground in the way governments approach investment in society’s most vulnerable communities.

    Hugh uses data in actuarial and advanced analytics projects to improve government policy

    He is a prolific commentator and author in mainstream media and at speaking events, bringing a public spotlight to the profession, especially in tackling some of the most complex issues facing society. In 2020, he led the development, and was media spokesperson for the Australian Actuaries Intergenerational Equity Index (AAIEI), and the Green Paper Mind the Gap – The AAIEI, which he co-authored with Taylor Fry colleagues Ramona Meyricke and Laura Dixie.

    Most recently, in 2021, he again demonstrated his commitment to rigorous research and development in an update to the AAIEI, launching a second Green Paper A narrow escape? The 2021 AAIEI. This Green Paper series has attracted significant media attention and accolades to the profession, with Hugh featured in publications spanning the Sydney Morning Herald, The Australian Financial Review and The New Daily.

    Beyond these recent milestones, Hugh has enjoyed a long and productive association with the Actuaries Institute. In addition to winning Institute awards including the Public Policy Essay Competition (2017) and the AM Parker Prize for most outstanding paper (2011), he was a member of the Data Analytics Practice Committee for three-and-a-half years, and currently sits on the Institute’s Public Policy Committee. In his role as Data Analytics Editor on the Actuaries Digital Editorial Committee, Hugh also pens the regular column Normal Deviance on topics of interest and urgency affecting the industry.

    The combination of Hugh’s impressive body of work, media savvy and numerous awards are testament to his extraordinary skill in bringing actuaries and their highly specialised work to a broad audience, and articulating their growing importance in solving real-world problems.

    Congratulations Hugh on this well-deserved achievement.

    This is an edited version of an original article published by Actuaries Digital.

  • RADAR 2021

    Welcome to RADAR, Taylor Fry’s inside look at the general insurance industry, the state of the market and what it means for insurers.

    In another head-spinning but generally improved year, the issues are big and nuanced – with COVID-19, new customer regulations and climate change the biggest of all. The impacts are mixed and wide ranging, from ongoing positive effects in motor, to the risk of increasing mental health claims in workers compensation and the significant insurer obligations towards improving customer outcomes across all lines.

    Add to this the shockwaves of the IPCC climate report, cybersecurity concerns for directors and officers, and the urgency of affordability – as householder premiums continue to rise yet the class remains unprofitable – and it’s clear the challenges are complex. Rising to them will require depth, insight and agile thinking. In our class-by-class analysis, we carefully unpick the issues to make sense of the way forward …

    Overall profitability

    General insurers rebounded from a disappointing FY2020, with an overall net profit after tax up by 17.6% in FY2021, with premium increases particularly evident in householders, domestic motor and professional indemnity. Reductions in gross claims were achieved despite significant increases in provisioning for COVID-19-related business interruption (BI) claims and the high cost of natural catastrophe claims in FY2021.

    Impacts of COVID-19

    Insurers continue to be significantly but variously impacted by COVID-19, with BI provisions an area of focus. Insurers eagerly await a decision on the second BI test case in September 2021, after increased BI provisions saw a spike in commercial property claims in Q420, following the first COVID-19 BI test case.

    Ongoing border closures and restrictions on movement continue to have positive effects in motor, experiencing fewer collision claims, but negative effects for travel insurance. Looking forward, COVID-19 impacts may reduce as vaccination take-up rates improve and lockdowns are eased.

    Affordability impacted by catastrophe events

    Several large natural catastrophe events impacted property insurers during FY2021, most notably the  Halloween hailstorm in central Qld ($940m industry loss), floods in the Hunter Valley and mid north coast ($650m industry loss), and tropical Cyclone Seroja ($273m industry loss).

    In an effort to address affordability, a reinsurance pool will commence in July 2022, covering cyclone and flood-related damage in Northern Australia, backed by a $10 billion government guarantee.

    Climate change

    The potential for climate change to increase the cost of natural disasters remains a key concern. The latest assessment report from the Intergovernmental Panel on Climate Change (IPCC), released in August 2021, found that climate change and its impacts on extreme weather events were accelerating.

    In recognition of escalating climate change risks, the government allocated $600m in funding for a National Recovery and Resilience Agency to develop initiatives that reduce the risk and lessen the impact of catastrophic weather events on communities.

    Mental health

    Workers are at increased risk of psychological claims, with the additional pressure created by changes in work demands, restrictions on movement and working from home. Primary mental injuries have increased in some publicly underwritten states, with potential to be a future cost pressure also for privately underwritten states.

    Consumer regulations

    FY21 was an important year for insurers implementing new consumer regulations, especially in addressing conduct and disclosure obligations. D&O in particular is a changing landscape, as company officers come to grips with complex, fast-changing risks, such as cybersecurity, as well as the pandemic and climate change. On the flipside, while class actions have adversely impacted D&O claims over several years, recent continuous disclosure and litigation funding reforms may help stem the growth in class actions in future.

    Download RADAR for more expert insights on the shifts and trends in the industry to help you navigate the uncertainty and discover opportunity in our evolving insurance landscape.

  • Data privacy – could traditional approaches work for machine learning models?

    In the second of our two-part series on privacy in the age of big data, we explore the potential to apply data privacy approaches used in traditional settings to machine learning models. We also look closely at emerging approaches such as ‘machine unlearning’, and why the search for commercially robust solutions to help organisations comply with privacy requirements is no simple task.

    Our lives are increasingly tied to artificial intelligence and machine learning, yet the consequences seem unclear – especially for our privacy – as countries scramble to navigate and keep pace with a world dominated by algorithms.

    What does this mean for our privacy in Australia? In Part 1 of our series, we looked at changes to the Privacy Act 1988 under consideration by the Australian Government, and how these might impact machine learning models, the industries who use them and the consumers they target. While the review is still underway, we identified some practical steps organisations can take now to assess and reduce potential privacy implications of the proposed changes for their machine learning models and pipelines. This leads us to ask, could current approaches to protect people’s data in traditional data contexts – for instance, when sensitive information needs to be masked in government or company data – also be applied to machine learning models as we adapt to this changing privacy landscape?

    Finding ways to keep private data hidden that work for business is increasingly challenging

    In considering the question, we explore:

    1. The challenges in applying data privacy approaches in traditional data contexts
    2. A traditional data privacy approach and its applicability for machine learning – Differential privacy is a system that allows data about groups to be shared without divulging information about individuals. We look at whether its principles can be applied to machine learning models to prevent privacy attacks that allow probabilistic private information about individuals to be inferred, or deduced, with an accuracy significantly greater than a random guess.
    3. Emerging approaches – We investigate whether ‘unlearning’ techniques can be used to reduce the costs and time associated with retraining models in response to requests to delete personal information by customers under the ‘right to erasure’, one of the proposed changes to the privacy act.

    1. Challenges of applying data privacy in everyday settings

    At this stage, the application of data privacy approaches to machine learning models is still a maturing research area. Even in traditional data contexts, masking private information can be difficult, and unexpected privacy issues can still arise even after using standard de-identification techniques that are well developed and commonly implemented.

    For example, the Australian Federal Department of Health unintentionally breached privacy laws when it published de-identified health data records of 2.5 million people online in 2016. Despite the published dataset complying with protocols around anonymisation and de-identification, it was found that the data entries for certain individuals with rare conditions could easily be re-identified by cross-referencing the dataset with a few simple facts from other sources such as Wikipedia and Facebook.

    Re-identifying de-identified data – it’s a worldwide risk

    Re-identification risks following the public release of granular datasets are not unique to Australia, with several recent cases emerging around the world. One such case relates to the National Practitioner Data Bank (NPDB), which is the national database for medical malpractice reports and disciplinary action in the United States. Although the names of individual doctors were removed in the publicly available de-identified dataset, several journalism organisations published investigative reports in 2011 that proved it was possible to match de-identified NPDB data entries to a specific doctor by cross-referencing other publicly available information. In response, the United States Department of Health and Human Services was forced to introduce a strict data use agreement stipulating that users must only use the data for statistical analysis, and specifically not to identify doctors and medical providers.

    Search for solutions

    These two examples demonstrate that even with the correct application of de-identification techniques, challenges commonly arise from the collation of released datasets with other publicly available information. This is a particular issue for granular datasets and individuals with unusual circumstances, often referred to as outliers.

    It’s not all bad news, however, and several techniques are emerging to address these data privacy risks, as the quest to find solutions gains momentum. We explore some of these below and whether they might be applicable in machine learning environments.

    Publicly sharing aggregate statistics gives a bird’s eye view without revealing an individual’s data

    2. Differential privacy – a modern approach for traditional data contexts

    In addition to releasing granular datasets, it is also common for companies and governments to share aggregate statistics and other high-level information about individuals within their datasets. Under normal circumstances, it can even be possible for information about specific individuals to be ascertained from these aggregate statistics, provided there is sufficient background information available on individuals within the population.

    How to share without getting personal

    Developed by researchers at Microsoft in 2006, differential privacy is a system that permits the public sharing of aggregate statistics and information about cohorts within datasets, without disclosing private information about specific individuals. It ensures that knowledge of the individual cannot be ascertained with confidence, regardless of what other information is known.

    In practice, differential privacy is implemented by adding noise or randomness to a dataset in a controlled manner such that aggregate statistics are preserved. This approach means it is still possible to learn something about the overall population, but it is much more difficult (if it is feasible at all) to breach privacy as attackers cannot confidently extract exact values of private information data for individuals.

    Fit for outwitting attackers

    To illustrate, we consider a simple example of a dataset that contains information on whether individuals prefer to exercise during the day or at night.

    Instead of publishing information on the specific individuals exercising at each time, statistics such as the mean or variance may be computed and shared based on the aggregate data to help protect individuals’ privacy. For instance, the published results might reveal that 70 out of 100 individuals prefer to exercise during the day, but not which exact people.

    However, without differential privacy implemented, it may still be possible for a malicious attacker to use these aggregate statistics, along with information on a sufficient number of individuals’ exercise preferences, to infer private information for the remaining individuals within the dataset.

    Make some noise with the flip of a coin

    Differential privacy techniques can be implemented to address these risks. In its simplest application, random noise can be added through the flipping of a coin for each entry of the Exercises day or night? column (or field) in the data, as we illustrate in the diagram below. If the flipped coin shows heads, then no adjustment is made and the true entry of the Exercises day or night? column is returned. On the other hand, if the flipped coin shows tails, the coin is flipped again and the entry adjusted to be day (heads) or night (tails). These arbitrary small substitutions protect individuals’ privacy as it means that potential attackers can never know with certainty whether the output is randomly generated or the truth.

    After the introduction of random noise, the statistics may reveal that the number of people who prefer to exercise during the day is 68 or 73, rather than the exact number of 70. This inaccuracy helps to preserve the privacy of individuals but has very little impact on the patterns of groups within the dataset – around 70 per cent of people still prefer to exercise during the day.

    Introducing inaccuracy could thwart an attacker but preserve patterns and protect people’s privacy

    Well-deserved reputation for keeping people’s data safe

    Differential privacy makes it possible for companies and governments to collect and share aggregate information about individuals’ behaviour, while maintaining the privacy of individual users. It has earned a well-deserved reputation providing principled and powerful mechanisms for ensuring privacy, and is an increasingly common approach in data governance settings. For example, Facebook has used differential privacy to protect data made publicly available to researchers analysing the effect of sharing misinformation on elections, while Uber has used it to detect statistical trends in its user base without exposing personal information.

    Applying differential privacy to machine learning models

    In broad terms, the introduction of noise under differential privacy conflicts with the philosophy of machine learning models, which typically rely on individual variation. Nevertheless, researchers have developed tools to apply differential privacy in machine learning, with the goal of limiting the impact of individual records used in the training dataset (data that helps to ‘train’ an algorithm or machine learning model) – particularly sensitive features – on model outputs. In turn, this limits the information about individuals that can be inferred from the model and its outputs.

    Differential privacy can be implemented in machine learning algorithms in different ways depending on whether the task is supervised or unsupervised learning (under unsupervised learning, models work on their own, typically with unlabelled data, to discover patterns and information that were previously undetected). Common places where noise can be introduced into machine learning models include the training dataset, the predicted model outputs and gradients (in simple terms, the speed at which a machine learning model ‘learns’).

    Adding ‘noise’ or randomness to a dataset puts a barrier between attackers and private information

    Model performance vs privacy protection – a precarious balance

    However, studies to date have found that while current mechanisms to apply differential privacy to machine learning models can reduce the risk of privacy attacks, they come at the cost of model utility and rarely offer an acceptable balance between the two. This means differential privacy settings that add more noise in order to provide strong privacy protections typically result in useless models, whereas settings that reduce the amount of noise added in order to improve model utility increase the risks of privacy leakage.

    The cost to model utility is also reflected in the Warfarin study we discussed in Part 1 of our series, which considered a regression model that predicted the dosage of Warfarin using patient demographic information, medical history and genetic markers. Researchers also showed that the use of differential privacy techniques to protect genomic privacy substantially interfered with the main purpose of this model, increasing the risk of negative patient outcomes such as strokes, bleeding events and mortality beyond acceptable levels.

    The hard truth about preventing privacy attacks

    Despite differential privacy’s reputation, it cannot yet be implemented for challenging tasks such as machine learning models without substantial privacy compromises being made to preserve utility. Researchers concluded that alternative means of protecting individual privacy must be used instead in settings where utility and privacy cannot be balanced, especially where certain levels of utility performance must be met.

    Achieving effective model performance and privacy protection is an evolving balancing act

    3. ‘Unlearning’ techniques

    Also in Part 1, we explored the implications of the ‘right to erasure’ for machine learning models, and found that in addition to the deletion of the individual’s data itself, any influence of the individual’s data on models may also be required to be removed upon customer request.

    Striving for efficiency

    The most straightforward approach to achieve this is to retrain machine learning models from scratch using an amended dataset excluding the individual’s data, but this is often computationally costly and inefficient, particularly for large datasets and frequent erasure requests.

    Alternative ‘unlearning’ techniques have been developed with the aim of avoiding these inefficiencies. These techniques are applied to ensure that a model no longer uses the data record that has been selected for erasure – in other words, they guarantee that training a model on a person’s data record and unlearning it afterwards will produce the same model distribution as if it were never trained on the data record at all. But ‘forgetting’ data is not an easy path for a model.

    Why is unlearning so challenging for machine learning models?

    Applying and implementing unlearning techniques for machine learning models is not straightforward for the following reasons:

    • Limited understanding of how each data record impacts the model and its parameters – Little research has been conducted to date to measure the influence of a particular training record on parameters for most machine learning models, with the few techniques tested so far found to be computationally expensive for all but the simplest of machine learning models.
    • Randomness in training methods and learning algorithms – A great deal of randomness exists in the training methods for most complex machine learning models, for example small batches of data are randomly sampled from the training dataset during model training. By design, learning algorithms are applied to search a vast hypothesis space (the set of candidate models from which the algorithm determines the best approximate for the target function).
    • Incremental training procedures – For most machine learning, the development process is incremental, meaning that an initial model is developed and then incrementally improved or updated as new data becomes available. As such, it is complex to remove the impact of training a model on an individual training record at a particular stage, as all subsequent model updates will depend on that training point, in some implicit way.

    Break it down – honing in on ‘slices’ and ‘shards’ of data

    One emerging unlearning technique that has been designed to overcome these challenges is Sharded, Isolated, Sliced and Aggregated (SISA) training, a framework that speeds up the unlearning process by strategically limiting the influence of an individual data record during training.

    Under SISA training, the training data is divided into multiple shards or pieces so that a single shard becomes a separate data record. By training models in isolation across each of these shards, only the affected models will need to be retrained when requests to erase an individual’s data are made, limiting retraining costs as each shard is smaller than the entire training dataset.

    In addition, each shard’s data can be further divided into slices and presented incrementally during training, rather than training each model on the entire shard directly. Slicing further decreases the time taken to unlearn, albeit at the expense of additional storage, as model retraining can be started from the last known point that does not include the data record to be unlearned (identified from records of the model parameters that are saved before introducing each new slice).

    SISA training divides data into smaller shards to assist models in unlearning a person’s information

    DaRE to dream – random forests spread their roots

    Another emerging technique that supports adding and removing training data with minimal retraining is data removal-enabled (DaRE) forests, a variant of random forests, which are a popular and widely used machine learning model that consists of an ensemble of decision tree models (another type of machine learning model that successively splits the data into different segments along ‘branches’ and ‘leaves’).

    DaRE makes retraining more efficient through two techniques:

    • Reducing dependency of the model structure on the dataset
    • Only retraining portions of the model where the structure must change to match the updated dataset.

    DaRE randomises both the variables used and the thresholds adopted for splitting in the upper layers of trees so that the choice is completely independent of the dataset and so this part of the model never needs to be changed or retrained. As splits near the top of each tree contain more data records than splits near the bottom and are therefore more expensive to retrain, strategically placing random splits near the top of the tree avoids retraining the parts that are most costly.

    This randomised structure also helps to reduce the retraining required, as individual data records are isolated to certain parts of the tree (‘subtrees’). When adding or removing data, stored data statistics for each level of the subtree are updated and used to check if a particular subtree needs retraining, which limits the number of computations through the data.

    But are these techniques any good?

    Studies using real-world datasets have shown that both of these techniques are materially faster than retraining models from scratch, while sacrificing very little in predictive model performance. For instance, researchers found that, on average, DaRE models were up to twice as fast as retraining from scratch with no loss in model accuracy, and two to three times faster if slightly worse predictive performance was tolerated.

    However, techniques do not always provide the expected benefits. Testing revealed that these speed-up gains from SISA training exist only when the number of erasure requests is less than three times the number of shards. Care must be taken when increasing the number of shards, as using a smaller amount of data to fit each model may make them less accurate, particularly for complex learning tasks.

    The fine print

    Other drawbacks of these emerging techniques are the large storage costs associated with them and their limited applicability across all machine learning algorithms. For instance, SISA training works best when models learn by iterating through the data (such as via stochastic gradient descent) and is not suitable for algorithms that must operate on the entire dataset at once.

    There are also likely to be challenges in implementing them in practice, as these approaches cannot be retrofitted onto current systems and would require retraining of existing models and a fundamental redesign of existing machine learning pipelines with unclear effects.

    DaRE reduces the need to retrain models to ‘unlearn’ data by splitting upper parts of decision trees

    The future looks …?

    The proposed changes to the privacy act may place significant governance and compliance burdens on organisations. Moreover, if tough positions are taken on items such as privacy of inferred data and right to erasure, then it may not even be feasible for organisations to comply with these requirements while continuing to operate complex and evolving machine learning systems.

    Although the application of existing data privacy approaches and emerging unlearning techniques to machine learning have shown some promise, this area of research is still in the very early stages of development. We cannot be certain that further research will result in commercially robust solutions that allow organisations to avoid investing in onerous and expensive procedures to ensure compliance. As shown by the unacceptable utility-privacy compromise for differential privacy, there may also be some fundamental limitations on achieving compliance via shortcuts.

    In future, it will be important to promote and invest in research for solutions that maintain privacy, while also providing other desirable model properties such as transparency and explainability. In the interim, if the proposed amendments to the privacy act are enacted and interpreted as applying to machine learning models, organisations may be forced to significantly simplify their modelling approaches and infrastructures to have a better chance of meeting compliance obligations.

  • Australian Actuaries Intergenerational Equity Index Update

    The 2021 Australian Actuaries Intergenerational Equity Index update and accompanying Green Paper show the equity gap between Australia’s generations closed slightly after ‘a year like no other: 2020’.

    Commissioned by the Institute and developed by Taylor Fry’s Hugh Miller, Ramona Meyricke, Laura Dixie and Matthew Bray, the Index takes a broad view of 24 indicators across six domains to track how wealth and wellbeing for different generations change over time. The domains include economic, housing, social, health and disability, education, and the environment.

    The update released today shows a drop in the values for those aged 65 to 74 years of age and an increase for those aged 45 to 54, and 25 to 34. This reversal breaks a seven-year streak of growing inequity, between the youngest and oldest cohorts.

    The Index shows that 2020 is an interesting mix of temporary spikes, continuation of long-term trends, and opportunities to innovate in the policy space.

    For more information, head over to the Actuaries Institute website.

  • The Australian privacy act is changing – how could this affect your machine learning models?

    Countries across the globe are grappling with how to protect people’s privacy in the age of big data. In the first of a two-part series, we look at changes to the privacy act under consideration, and how to address the potential impacts for industry and consumers in a world increasingly tied to artificial intelligence and machine learning.

    Community concerns have become more urgent in recent years regarding the way businesses collect, use and store people’s personal information. In response to a recommendation from the Australian Competition and Consumer Commission’s (ACCC) Digital Platforms Inquiry (DPI) – the Australian Government is reviewing the Privacy Act 1988 to ensure privacy settings empower consumers, protect their data and best serve the Australian economy.

    Of the several proposed legislative changes, we outline three scenarios being considered and how they may impact organisations that collect and process customer data – in particular, those organisations that use machine learning algorithms in privacy-sensitive applications, such as predicting lifestyle choices, making medical diagnoses and facial recognition. We break down the three proposed changes to the privacy act below:

    1. Expansion of the definition of personal information to include technical data and ‘inferred’ data (information deduced from other sources)
    2. Introduction of a ‘right to erasure’ under which entities are required to erase the personal information of consumers at their request
    3. Strengthening of consent requirements through pro-consumer defaults, where entities are permitted to collect and use information only from consumers who have opted in.

    Algorithms used in privacy-sensitive applications such as lifestyle choices may be affected

    1. Treating inferred data as personal information

    As part of the proposed changes to the privacy act, the Government is considering expanding the definition of personal information to also provide protection for the following:

    • Technical data, which are online identifiers that can be used to identify an individual such as IP addresses, device identifiers and location data.
    • Inferred data, which is personal information revealed from the collection and collation of information from multiple sources. For example, a data analytics company may combine information collected about an individual’s activity on digital platforms, such as interactions and likes, with data from fitness trackers and other ‘smart’ devices to reveal information about an individual’s health or political affiliations.

    How will this affect consumers, organisations and models?

    The possibility of including inferred data as personal information in the privacy act represents a fundamental expansion in what organisations might think of as personal information. Typically, it is considered to be information provided by a user or trusted source that is known with a reasonable amount of certainty. For example, an organisation will know a customer’s age by requesting their date of birth.

    In contrast, inferred information can usually only ever be known probabilistically. Under the proposed change, knowledge such as ‘there is an 80% probability that this customer is between 35 and 40’ could be treated the same way as knowledge such as ‘this customer is 37’.

    This means model outputs may become ensnared in restrictive governance requirements because inferred customer information is often generated as an output of machine learning models. There is even a possibility that governance requirements may be extended to the models themselves, which have been shown to leak specific private information in the training data (data used to ‘train’ an algorithm or machine learning model) to a malicious attacker. The consequences for machine learning model regulation are potentially hugely significant for consumers and organisations, given personal information is subject to many more rights and obligations than the limited set currently applicable to models.

    In addition, newly afforded rights for consumers may mean that they can request information on model origination or trading, and restrict future processing and use of models. On top of this, companies may now be required to design models that comply with data protection and security principles, and to discard models in order to comply with storage limitation principles.

    There are many challenges in protecting against unintended privacy leakages from models

    When machine learning models leak private information

    Privacy attacks on machine learning models can be undertaken with full access to a model’s structure (‘white box’ attack) or limited query access to a model’s observable behaviour (‘black box’ attack). Through this process, it is possible to infer probabilistic private information about an individual with a success rate significantly greater than a random guess.

    Medical leaks

    For example, US studies were performed on a regression model that predicted the dosage of Warfarin, a widely used anticoagulant, using patient demographic information, medical history and genetic markers. Researchers reverse engineered a patient’s genetic markers using only black-box access to the prediction model and demographic information about patients in the training data – with a success rate similar to a model trained specifically to predict the genetic marker.

    Uncanny facial recognition

    Recent studies have also demonstrated that recognisable images of people’s faces can be recovered from certain facial recognition models given only their name and black-box access to the underlying model to the point where skilled crowd workers could use the recovered photos to identify an individual from a line-up with 95% accuracy. The picture below on the left was recovered with only a name and limited ‘black box’ access to a model. It is eerily similar to the actual image on the right, which was used to train the model.

    Source

    A problem with predictive text

    Privacy leakage is particularly problematic for generative sequence models like those used for text auto-completion and predictive keyboards, as these models are often trained on sensitive or private data such as the text of private messages. For these models, the risks of privacy leakage are not restricted to sophisticated attacks, but may even occur through normal use of the model.

    For example, model users may find that ‘my credit card number is …’ is auto-completed by the model with oddly specific details or even obvious secrets such as a valid-looking credit card number. Protecting against this sort of leakage is surprisingly challenging, with research indicating that unintended memorisation can occur early during training, and sophisticated approaches to prevent overfitting are ineffective in reducing the risk of privacy leakages.

    Challenges in preventing privacy leakages

    Machine learning models tend to memorise their training data, rather than learning generalisable patterns, unless specific care is taken in their construction – a phenomenon known as ‘overfitting’.

    Unsurprisingly, theoretical and experimental results have confirmed that machine learning models, including regression and target classification models, become more vulnerable to privacy attacks the more they are overfit. What is a lot more surprising is that, while reducing overfitting can offer some protection, it does not completely protect against privacy leakage. Studies have found that models built using stable learning algorithms designed to prevent overfitting were also susceptible to leakage.

    Consumers may gain the right to erase their data from a model, causing concerns for business

    2. Right to ‘erasure’ – deleting personal information by customer request

    Put into effect across the European Union in 2018 and sometimes known as the ‘right to be forgotten’, the broad ranging General Data Protection Regulations include a ‘right to erasure’, which provides European citizens with a right to have their personal data erased under certain circumstances, including when consumers have withdrawn their consent or where it is no longer necessary for the purpose for which it was originally collected and processed. This serves as a reference point for similar potential rights in the Australian Government’s review of the country’s privacy act.

    Why organisations are cautious

    Although organisations broadly support the introduction of a right to erasure, concerns have been raised about the potential negative impact the deletion of data may have on businesses and public interest. In its submission, Google considers it “important to include a flexible balancing mechanism or exceptions to such a right so as to enable businesses to consider deletion requests against legitimate business purposes for retaining data”.

    Other organisations have proposed that any ‘right to erasure’ needs to be subject to appropriate constraints, which balance requests against legitimate business reasons, compliance with existing regulatory obligations and the technical feasibility and operational practicalities of implementation.

    What could the ‘right to erasure’ mean for machine learning models?

    Given machine learning models can be considered as having processed personal information, a consumer may wish to exercise their right to erase themselves from a model to remove unwanted insights about themselves or a group they identify as being part of, or to delete information that may be compromised in data breaches. Consumers may also seek to prevent the ongoing use of models that incorporate their data to prevent companies from continuing to derive a benefit from having historically held their information.

    What would it mean for business?

    In most circumstances, the removal of a single customer’s data is unlikely to have a material influence on a model’s structure. The ‘right to erasure’ becomes more powerful when exercised collectively through a co-ordinated action by a group of related customers, as their data is more likely to have had a material influence. For example, the use of facial recognition technology for identifying a marginalised group may cause a collection of customers to feel they are disadvantaged by the ongoing use of models trained on their data.

    An immediate challenge is what constitutes a group before the right to erasure applies? Pragmatically, it would be difficult to define a general rule and it is plausible that even an erasure request from a single customer would require the removal of their data from the model, as well as their exclusion in the processing of data. This would be a very tall order for organisations to comply with, to the point of being unworkable in some situations where the cost and time required to comply with erasure requests rapidly outweighs the benefits of using a machine learning model at all.

    Organisations are cautious about proposals to pre-select digital consent settings to off

    3. Strengthening consent – how will it affect model insights?

    What pro-consumer defaults really mean

    With consumers preferring digital platforms collect only the information they need to provide their products or services, the final ACCC Digital Platforms Inquiry report recommended that default settings enabling data processing for purposes other than contract performance should be pre-selected to off, otherwise known as ‘pro-consumer defaults’.

    Why organisations are cautious

    While organisations strongly support improved transparency for consumers through meaningful notice and consent requirements, they caution against proposals that would force businesses to provide long, complex notices or separate consents for each use of personal information.  They argue that these approaches would cause consumers to switch off and not meaningfully engage with relevant privacy notices and controls, a phenomenon known as ‘consent fatigue’.

    So do modellers have to start from scratch?

    The potential implication of pro-consumer defaults is that the data available to organisations for future training of machine learning models may be limited, as it can be reasonably expected that relatively few consumers would make the effort to deliberately reverse these settings.

    Consider an extreme scenario, whereby historical data that was collected prior to the introduction of the laws is no longer permitted to be used, through the new pro-consumer default settings. Many organisations may struggle in the weeks immediately following the change, and could effectively be required to rebuild models from scratch at a time when very little data may be available.

    Could privacy protections lead to misleading model insights?

    Problems could also arise where the profile and characteristics of customers that opt-in to data processing are materially different from the wider customer base who choose the default settings. These issues are likely to be more significant for analysis that is used to support operational and strategic decisions, as model insights may be based on a skewed view of customer behaviour.

    Assessing your privacy risks – steps you can take now

    With the review still underway, the final form of the changes made to the privacy act remain uncertain, with the potential ramifications for machine learning models even more so.

    Nevertheless, there are some practical steps organisations can take now to assess and reduce potential privacy implications for their machine learning models and pipelines:

    • Establish or review the composition of a cross-functional working group – The selection of key staff would define the technical, governance and compliance-related tasks that need to be completed, and identify who owns the process in areas such as analytics, privacy, legal, product owners and data.
    • Review data usage policies – These should include explicit policies for how to use certain types of data and in which contexts, so that a consistent approach is maintained across the organisation.
    • Track and document the use of customer data in models – This should include collating the following details for all existing models and pipelines: Original source of the data; applicable privacy statements for each data item and source; how and where the data is used in modelling processes; where possible, the contribution of each data source to model and organisational performance; if warranted, explicit testing of the impact on models of removing specific customer information, particularly for more sensitive information.

    Taking these steps will provide organisations with a good view of where privacy risks may arise, and ensures they are better prepared for the potential implications of changes arising from the review of the privacy act.

    In Part 2 of our ‘machine learning and the privacy act’ series, we explore the potential to apply existing data privacy approaches to machine learning models, what emerging approaches such as ‘machine unlearning’ have to offer, and the search for commercially robust solutions for complying with privacy requirements.

  • Where are the businesses most reliant on JobKeeper (January)?

    As Australian businesses face their first month without the JobKeeper scheme, we look at how the take-up of the scheme has changed since it started in April 2020 to the latest data release which covers payments to the end of January 2021. Our map covers the whole of Australia by local government area, and shows the proportion of businesses receiving the payments has varied significantly by region.

    The JobKeeper Payment scheme was a temporary wage support measure for businesses significantly affected by COVID-19. The scheme had three phases, each with their own qualification requirements:

    • Phase 1 ran from April to September 2020
    • Phase 2 ran from October to December 2020
    • Phase 3 from January to March 2021.

    The latest data on the JobKeeper scheme reveals in January 2021, the first month of the third and final phase of JobKeeper, 15% of Australia’s 2.4 million businesses were receiving JobKeeper payments (372,000 businesses). The number of businesses qualifying for JobKeeper has been very stable throughout each individual phase, which means figures from January 2021 are likely to be a good indicator of the overall reliance on the scheme at the end of March 2021.

    At the height of the scheme, 40% of all businesses in Australia were registered to receive JobKeeper payments.

    Our map shows regional variability in the take up of JobKeeper by businesses, notably:

    • Melbourne’s second wave of COVID-19 infections throughout the winter and spring months of 2020 led to a heavy reliance on JobKeeper in the city. Throughout July and August 2020, 46% of Melbourne businesses were receiving JobKeeper payments. In the last phase of the scheme, beginning in January 23% of the city’s businesses were still dependent on the subsidy.
    • Similarly, Sydney’s December outbreak also seems to have had an impact on the city’s reliance on JobKeeper, albeit not to the same extent as in Melbourne.

    Taylor Fry Principal Alan Greenfield says, “The outbreaks and resulting restrictions incurred in Melbourne and Sydney have had a measurable impact on the demand for JobKeeper in those two cities. In the last phase of the scheme, 23% and 17% of businesses were on JobKeeper in Greater Melbourne and Greater Sydney respectively. This is vastly different to 13%, 13% and 11% for Brisbane, Adelaide and Perth, who have not experienced significant outbreaks or lockdowns.”

    Outside Australia’s capital cities, demand for JobKeeper was high during the first six months of the scheme, but businesses in regional areas have since been less reliant on the subsidy than those in capital cities.

    “The lower reliance on JobKeeper payments in regional areas is partly due to the mix of businesses in those areas, fewer restrictions on movement and smaller rate of change in consumer behaviour compared to cities. One exception is destination tourism areas like Byron Bay and Port Douglas where JobKeeper reliance was still relatively high towards the end of the scheme,” says Greenfield.

    About our map

    We’ve used the latest data (JobKeeper processed applications between April 2020 and January 2021) from the Treasury and the Australian Bureau of Statistics to estimate and map, the proportion of businesses in each Local Government Area (LGA) who have registered to receive the JobKeeper payment. LGAs with the highest proportion of its businesses registered to receive the payment are coloured red, and those with the lowest proportion are coloured green.

    The interactive map below shows JobKeeper reliance by Local Government Area over time (updated 7 April 2021).

    https://taylorfry.shinyapps.io/jobkeeper

    How do I use the map?

    Click on an LGA to see what proportion of its businesses are registered to receive the JobKeeper payment.

    Disclaimer

    This page and its contents herein, including all data, mapping and analysis (“Page”), copyright 2021 Taylor Fry, all rights reserved, is provided solely for information purposes. You should not rely on this page for financial advice. Use of the Page by commercial parties and/or in commerce is strictly prohibited. Redistribution of the Page is strictly prohibited. When linking to the page, attribute the Page as Taylor Fry’s COVID-19 Financial Impact Index. The Page relies upon publicly available data from multiple sources that do not always agree. Taylor Fry hereby disclaims any and all representations and warranties with respect to the Page, including accuracy, fitness for use, reliability, completeness, and non-infringement of third party rights. Any use of Taylor Fry’s names, logos, trademarks, and/or trade dress in a factually inaccurate manner or for marketing, promotional or commercial purposes is strictly prohibited. These terms and conditions are subject to change. Your use of the Page constitutes your acceptance of these terms and conditions and any future modifications thereof.

  • Cyber insurance – key issues for insurers

    Spurred on by the pandemic, technology use is on the rise – and, along with it, an increase in cyber attacks, making security a top concern for companies. We look at the growing area of cyber insurance and some of the new approaches insurers will need to succeed in this dynamic environment.

    With greater connectivity in every part of our lives – at work, home and socially – our devices and IT systems have never seemed more exposed. What is the role of cyber insurance in mitigating these risks, how has it evolved and where is it headed? While cyber insurance premiums have grown significantly in the past decade, it’s still a small class of business compared to more traditional liability coverages, with only a few insurers currently offering it in Australia. Despite take-up remaining low, especially among small-to-medium enterprises (SMEs), the market continues to grow, as cyber attacks gain in frequency and sophistication. Astute insurers will be exploring the many new ideas in underwriting and pricing to tackle their challenges now and in the future.

    What is cyber insurance?

    First things first – cyber insurance is an insurance product that protects businesses from financial risks relating to cyber incidents. Policies will usually cover:

    • First party losses – These are losses suffered directly by the insured business
    • Third party losses – These are costs incurred by the insured relating to a cyber event experienced by another party but where fault lies with the insured.

    Cyber insurance is usually defined as a liability product and is often sold as an extension to an existing standard business liability product.

    Cyber losses can also arise from traditional liability policies such as D&O if these policies do not explicitly exclude cyber risks. This is known as silent cyber or non-affirmative cyber cover. As cyber risks evolve over time, however, more insurers are clarifying cyber risk as a separate product and then excluding this risk from their standard liability policies. This means policyholders who require cyber cover need to explicitly take out a policy to cover this risk.

    The underlying risks cyber policies cover are rapidly changing over time

    A brief history

    Where did it all start? Insurance policies for cyber insurance were first developed in the late 1990s. Initially policies provided predominantly third-party cover for companies that provided IT services used by other businesses. As technology advanced and became integral for more companies, cyber insurance expanded, and insurers began offering first-party coverage to any company using technology.

    The cyber insurance scene today

    The growth in cyber policies has resulted in a range of coverage and exclusions in the products offered. Standard coverages for cyber policies, as distinct from more traditional liability coverages, include:

    • Business interruption costs
    • Network security costs
    • Costs arising from theft or fraud
    • Forensic investigation costs
    • Costs related to data loss and restoration
    • Extortion costs
    • Costs associated with any information privacy penalties.

    A changing landscape

    Another point that differentiates cyber insurance from other classes is that the underlying risks the policies cover are rapidly changing over time. As technology becomes more powerful and essential for all organisations, this provides greater opportunities for cyber criminals.

    One example is the increase in targeted ransomware attacks. Attackers using ransomware would previously target anyone they could trick into having a malicious payload delivered to install the ransomware. This was generally home users they would extort for a few hundred dollars to regain access to personal files and photos.

    Go phish – a worrying trend

    Now attackers are specifically targeting individual firms and blackmailing them for at least tens of thousands of dollars at a time. These attacks start with reconnaissance and then breaking into the company’s network, predominantly using targeted phishing attacks (otherwise known as spear-phishing). They then exfiltrate data from the company, downloading it to a remote location and encrypting as many files as possible using a scrambling algorithm – and only they have the key to it. They then demand a large sum of money to decrypt the file to restore network and system operations.

    As well as an increase in the number of cyber threats, the cost associated with data breaches is also increasing. The average cost of a data breach for Australian organisations was estimated to be $3.35 million in 2020. This was an increase of almost 10 per cent from the previous year. This increase in risk and costs means cyber insurance is becoming more of a necessity for organisations.

    Australia’s increasing regulatory focus

    In Australia, the focus on cyber risks and cyber insurance is increasing. On the regulatory front, the Australian Prudential Regulation Authority (APRA) introduced Prudential Standard CPS 234 in 2019. This standard requires that APRA-regulated entities “take measures to be resilient against information security incidents” and inform APRA of any material information security breaches.

    Under the standard, regulated entities must maintain an information security capability commensurate with the size and extent of threats to information systems to ensure continued operation. The standard does not mandate entities to hold cyber insurance.

    Sharp eye on data collection

    APRA is also currently consulting with insurers on extending its insurance data collection to separately collect premium and claims information for cyber insurance. Currently, cyber cover is included under the public liability class. The increase in cyber policies and limited availability of data for this class has been cited as the reason for the proposed change.

    This increase in focus is not just limited to the financial services. In November 2020, the Australian Government announced that a cyber security cabinet role will be created. This move has been in response to an increase in attempted cyber attacks during 2020. Several of these attacks have been on critical infrastructure providers. Many high-profile cyber attacks also occurred last year in Australia, including:

    • Toll Group, which had two separate ransomware attacks in January and April.
    • Regis Healthcare, which had sensitive data stolen in a ransomware attack in August.
    • Australian Defence Force recruiting system, which was taken offline for 10 days in February to contain a security breach.
    • Levitas Capital, which had its email system compromised by a bogus Zoom invitation. This resulted in $8.7 million in fraudulent invoices being paid. While this money was recovered, Levitas was forced to close its business due to clients withdrawing their funds as a consequence of the attack.

    Phishing scams targeting firms are netting attackers tens of thousands of dollars at a time

    Serious breaches ring in 2021

    Most recently, the new year had barely dawned when the Reserve Bank of New Zealand disclosed on 11 January it had suffered a serious data breach of its file-sharing service provided by California-based data protection firm Accellion.

    About two weeks later, Australian Securities and Investment Commission (ASIC) reported a cyber security breach, which had occurred on 15 January. The national corporate regulator said one of its servers used for transferring information, including credit licence applications, had been illegally accessed through the Accellion software.

    These incidents highlight how a weakness in a single piece of software can result in cyber events for several different companies.

    Varied corporate view of cyber insurance

    From an insurance perspective, cyber insurance take-up has been limited, particularly in the SME market. The Chubb 2019 Cyber Preparedness Report found only 27 per cent of Australian SMEs have cyber insurance. Some reasons for this low take-up by SMEs may be due to the belief that their existing liability insurance will cover any cyber risks, or a view that cyber risk is a relatively low risk.

    For larger corporates, cyber security is a key focus. As businesses have become more reliant on their IT systems with the increase in people working from home due to the COVID-19 restrictions, this has increased focus on the risks.

    Challenges in pricing for cyber

    Traditional insurance products such as motor, property and liability are generally priced by analysing past claims data against various rating factors. This analysis then allows insurers to estimate the expected future costs for their customers based on their declared rating factors, and this is used to set premiums. It’s an approach requiring a large amount of past claims and rating factor data. It also assumes the underlying risk associated with the product is not changing significantly over time.

    For cyber insurance, there is a limited amount of past data, given it’s a relatively new product, and the underlying risk is rapidly changing over time as technology advances. Cyber is different from other insurance products in that the risks transcend geographical borders, highlighting an urgent need for global solutions. Insurers are also generally protective of the exact approach they use for pricing, which adds an extra challenge.

    Some transparency in America

    In the United States, however, pricing structures are more transparent, and insurers are required to file policy details with state regulators. These filings include policy details and rating structures used to determine premiums. A 2019 study analysed these filings for cyber insurance policies in New York, Pennsylvania and California. This study found there were three main rating structures:

    • Flat rates – This is the same rate for all policies, or flat rates based on a small set of hazard groups. These rating structures tend to be used for policies offered to smaller companies.
    • Base rates with multipliers based on rating factors – This is a standard insurance rating structure used for other classes of insurance. The base rate is usually calculated as a function of the size of the insured (for example, based on revenue, assets or number of employees). The rating factors reflect the industry the insured is operating in, and may include retention limits and risk ratings.
    • Base rates with security questions – This is a more advanced version of the rating factor approach, where the rating factors reflect the cyber security measures the insured has in place. Under this rating structure, a company with more advanced cyber security would pay a lower premium than a company with less advanced cyber security measures, if all other features for the two companies were the same.

    Are these approaches sufficient to keep pace with evolving cyber risks? While they go some way to addressing current issues, it’s clear the industry needs to be agile if it’s to keep pace with the evolving cyber environment and looking at what might be next in adequately assessing risk.

    Australia’s increase in cyber crime

    In its latest cyber threat report, the Australian Cyber Security Centre (ACSC) has noted that “malicious cyber activity against Australia’s national and economic interests is increasing in frequency, scale and sophistication”. The report notes that “Australia’s relative wealth, high levels of online connectivity and increasing delivery of services through online channels make it very attractive and profitable for cybercrime adversaries”. Over the year to 30 June 2020, the ACSC responded to 2,266 cyber incidents, and also noted an increase in spear-phishing campaigns during the COVID-19 pandemic.

    The need to evolve

    This increasing underlying risk suggests traditional insurance pricing techniques also need to evolve to accommodate cyber insurance, so that insurers continue to adequately price the risks and that insured parties understand their specific vulnerabilities and what they can do to reduce their risk of being victims of cyber crime.

    Traditional insurance pricing and underwriting techniques are based on an annual review of an insured’s risk. Individual adjustments for the insured’s risk are often based on an underwriter’s knowledge of the insured, combined with the recent claims experience for the insured. The speed at which risks change for cyber perils means it’s important insured entities understand what controls they need to implement to reduce the risk and also what actions they could take to mitigate the risks if an attack occurred.

    Future-thinking insurers looking to respond dynamically will lead the way ahead

    Assessing risk – the new ways forward

    Recently, insurers have begun using scanning tools to assess the individual vulnerability for each insured entity. Companies such as UpGuard, BitSight and Security Scorecard provide scores that measure a company’s cyber security posture based on automated tests of the company’s online systems. These tools formulate a score based on system vulnerabilities, reputation risk, phishing and malware, email security and network security. As well as providing a measure of overall risk, the tools can also provide feedback on areas an insured company can address to improve its cyber resilience.

    In New Zealand, IAG recently launched a cyber security tool for SMEs, which has been developed in partnership with UpGuard. Brokers such as Willis Towers Watson and global network TechAssure are also developing similar services designed to assist companies to assess their cyber risks.

    Other tools insurers could use in their pricing and underwriting of cyber insurance include:

    • Dark web scans – These can be used to look for any mentions of the insured company that may indicate it’s a potential target, has been previously compromised or suffered a data breach.
    • Penetration testing – This is similar to the scanning tools mentioned above, but more intensive and targeted. The insurer’s security analysis team attacks the insured company’s systems to exploit vulnerabilities and effectively assess the strength of their security.
    • Managed service partnerships – By partnering with security service providers, the insurer could provide outsourced security management and monitoring services bundled into the policy.

    Proactive insurers for the win

    Cyber insurance is a rapidly evolving class of business, in terms of the underlying risks and the information available to insurers for pricing and underwriting. Forward-thinking insurers will be looking to supplement their traditional approaches with this new information. The standard bearers in this market will be the proactive insurers able to also provide advice to their customers on weaknesses in their cyber security, and respond dynamically, by way of improved terms or prices, to actions taken by their customers to mitigate these vulnerabilities.